

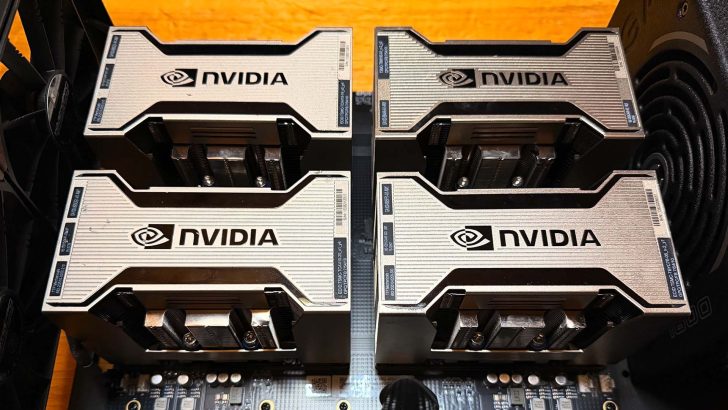
A recent test conducted by YouTube channel Jun Yamog evaluated the performance of four Nvidia Tesla V100 GPUs mounted on an NVLink carrier board. The setup utilized the Qwen3.8-Flash-Next benchmark to compare inference speeds against modern hardware, including two DGX Spark units and a Mac Studio equipped with the M5 Ultra chip.
The Tesla V100, released in 2017 based on the Volta architecture, features 32GB of HBM2 memory and 900GB/s bandwidth. The custom carrier board provides 300GB/s bandwidth via six NVLink 2.0 connections. To manage thermal output, the tester modified Nvidia A100 coolers to handle the 300W power consumption of each V100 unit.
In long-prompt processing, the four-GPU cluster outperformed the M5 Ultra by 230% and the DGX Spark cluster by 40%. During short-prompt tests, the V100 cluster maintained a 40% lead over the DGX Spark and was 163% faster than the M5 Ultra. The tester noted that software optimization may influence the performance gap with Apple Silicon.
Regarding short-prompt token generation, the V100 cluster achieved 100.6 tokens per second, surpassing the DGX Spark setup by 121%. In comparison, the M5 Ultra recorded 44.5 tokens per second. These results suggest that older data center GPUs retain significant throughput capabilities for specific AI inference workloads.



