

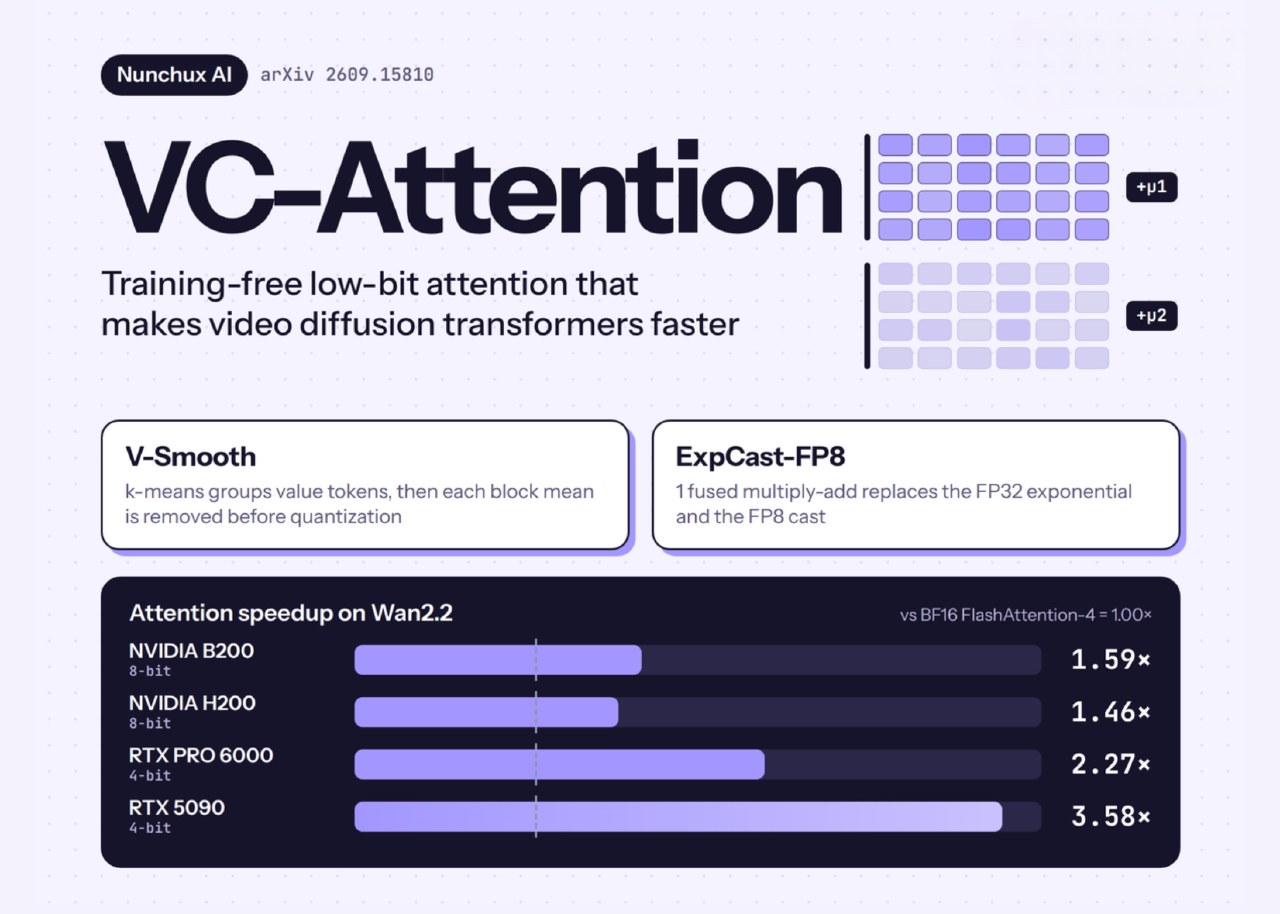
Nunchux AI has introduced VC-Attention, a training-free attention kernel designed to accelerate video diffusion transformers. The technology addresses performance bottlenecks in models like Wan2.2-14B, where attention operations can consume over 64% of generation time on hardware like the RTX 5090.
The kernel optimizes matrix products by utilizing low-bit Tensor Cores and an ExpCast-FP8 method that streamlines softmax calculations. By implementing a custom CuTe/CUDA fusion for the preprocessing chain, the company reduced a specific V-Smooth operation from 42.2 ms to 4.8 ms on the B200 GPU.
Testing across four open-weight models, including HunyuanVideo-1.5 and MiniMax-H3, showed significant speed improvements. On the B200, VC-Attention outperformed SageAttention2 by 6.02x. For MiniMax-H3 at 1344x768 resolution, the kernel achieved a 1.60x speedup compared to BF16 FlashAttention-4.
The company's proprietary extension, Nunchux Attention, further boosts performance, reaching 1.91x speedups on B200 hardware. The method is compatible with existing techniques such as sparse attention and multi-GPU execution. Nunchux plans to offer access to MiniMax-H3 via its Modelverse waitlist.



