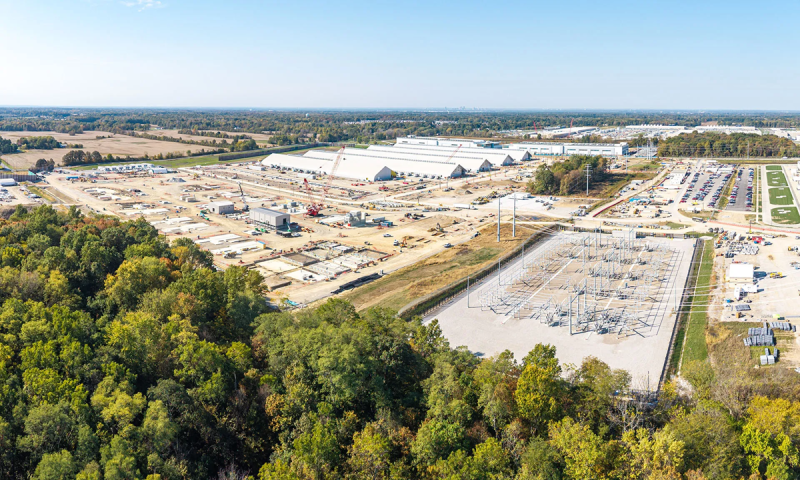
Meta is managing a massive AI supercluster in New Albany, Ohio, where over 11% of NVIDIA accelerators are currently idle or offline. These units serve as a hot standby pool, ready to replace active chips that fail during intensive model training sessions.
The company employs a strategy of keeping 8 out of every 72 accelerators in a hot standby state within each NVLink domain. This configuration helps mitigate the impact of hardware failures, which are inevitable in clusters containing tens of thousands of GPUs.
Meta has significantly improved operational stability, reducing training interruptions from 1,000 per day per 8,000 accelerators to approximately 11. The company now achieves a goodput rate exceeding 85% for pre-training and 90% for reinforcement learning tasks.
Technical challenges include managing over 600,000 NVLink connections in Blackwell-based systems and preventing power surges during large-scale cluster operations. Meta utilizes continuous telemetry and L11 stress testing to identify connection issues early.
The company aims to scale its infrastructure to one million accelerators. Future goals include reducing the interruption frequency to two per day per 8,000 accelerators and achieving a mean time between failures of 100,000 GPU-hours.