

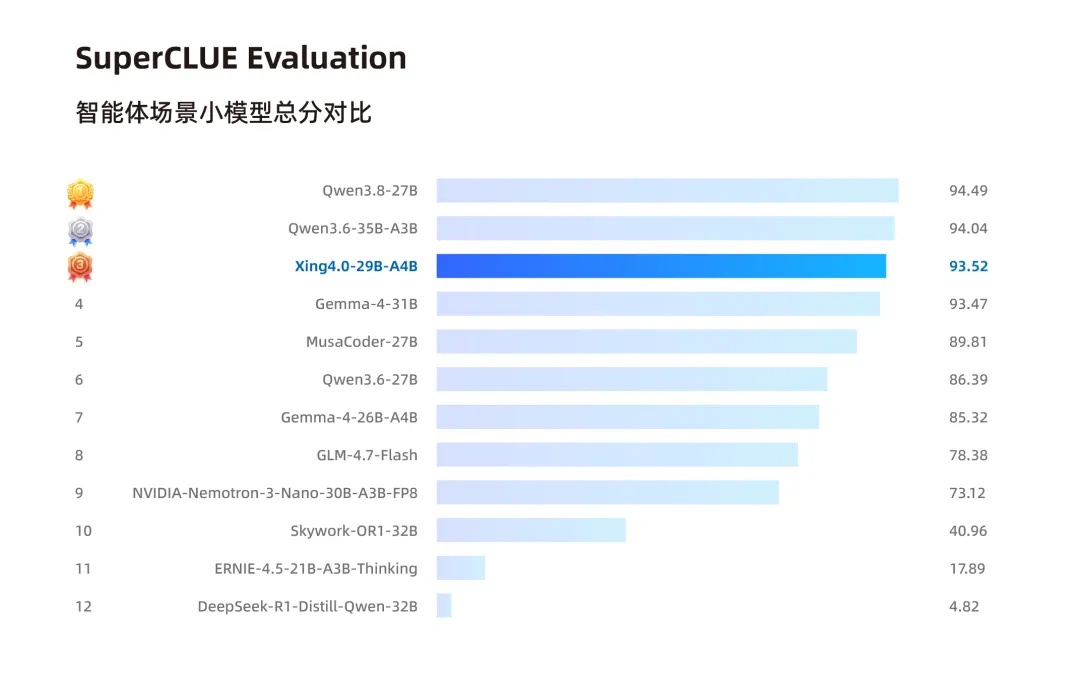
China Telecom AI Technology officially launched the Xing4.0-29B-A4B large language model on September 17. The model features 29 billion total parameters with 4 billion active parameters. It is designed for complex tasks including code development, data analysis, and office automation, with support for long-context processing.
Huawei announced that this is the first domestic model trained using the Ascend Atlas 900 A3 SuperPoD liquid-cooled cluster and the MindSpore framework. The architecture utilizes MLA for KV cache compression, MT for multi-token prediction, and mHC for numerical stability. Training sequences were scaled from 4K up to 256K.
The development involved a data system covering tens of trillions of tokens, including PB-level multi-source data cleaning and agent behavior trajectories. The team implemented a high-concurrency sandbox for synthetic data generation and automated verification to ensure accuracy throughout the pre-training and post-training lifecycles.
Engineering optimizations on the Ascend cluster improved training performance by 96%. Specific enhancements include a 32% throughput increase via expert load balancing and Grouped GEMM for the MoE architecture, a 19% boost from selective recomputation, and a 30% efficiency gain from Ascend C mHC fusion operators.
The model incorporates the Slime reinforcement learning framework to enhance reasoning and agent capabilities. Huawei currently supports native training for over 40 industry-leading models and remains the only domestic provider supporting commercial large-scale pre-training for SOTA models.



