

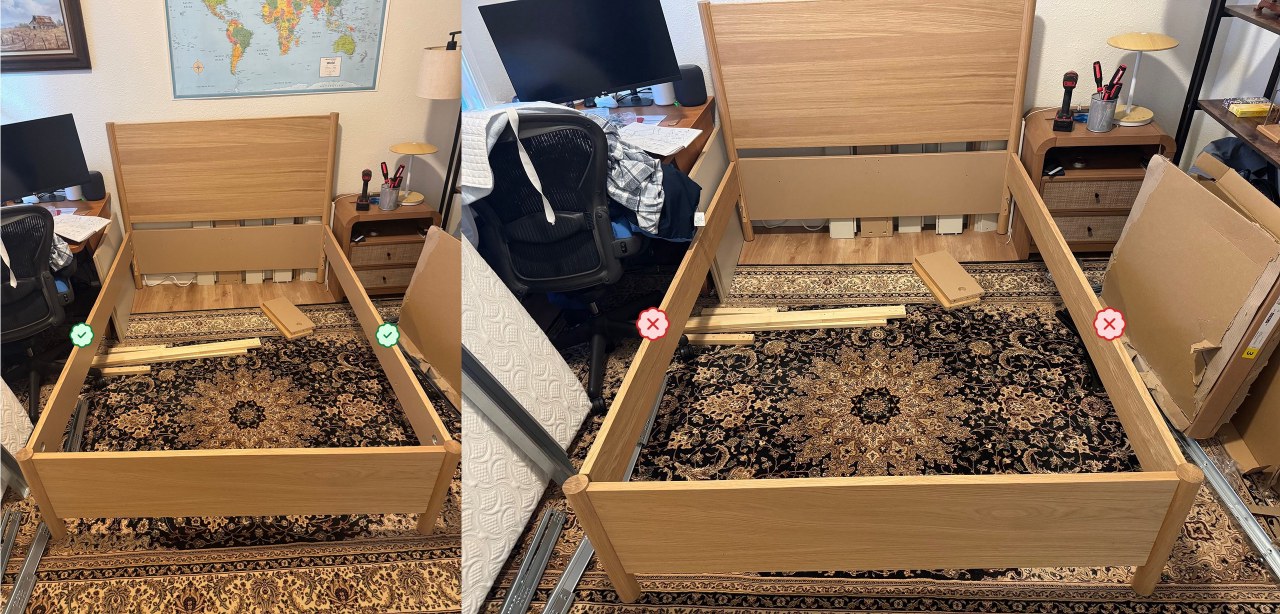
Epoch AI conducted the Furniture Assembly Benchmark (FAB) on September 23, evaluating how multimodal AI models identify assembly errors in IKEA furniture. The test uses 60 photos of intentionally misassembled furniture, requiring models to compare images against official PDF manuals using Python interpreters and image magnification tools.
OpenAI GPT-6 Astra achieved the highest accuracy at 80%, marking a significant improvement from the 28% accuracy recorded by Claude Opus 4.5 in November 2025. Anthropic models Claude Fable 5.1 and Claude Opus 5 followed with 70% and 61% accuracy, respectively. GPT-6 Astra also demonstrated superior efficiency, processing each image in approximately 3 minutes.
The research highlights that visual reasoning remains a challenge for some models. While Google Gemini and Alibaba Qwen models tend to assume errors exist, earlier versions of OpenAI and Anthropic models often failed to detect them. The study notes that error visibility and camera angles significantly impact performance, rather than the inherent complexity of the furniture.
Regarding Chinese models, the Kimi K3 open-weights model currently lags behind international leaders by approximately 7 months in visual reasoning tasks. Researchers observed that this gap is wider than in general capability benchmarks. Additionally, popular models such as DeepSeek V4 Pro and GLM 5.3 currently lack image processing support.



