

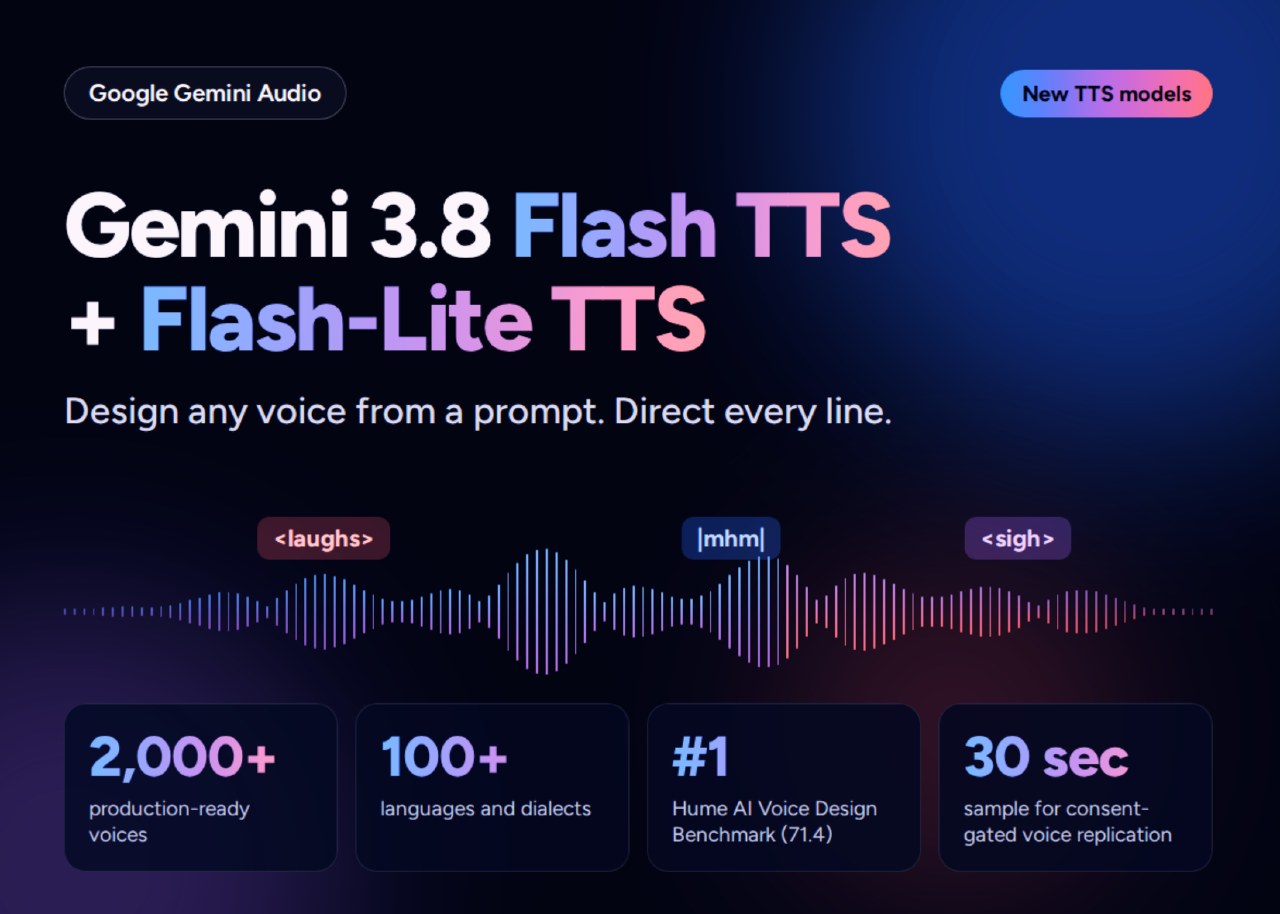
Google has launched two new text-to-speech models, Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. Both tools are currently available through the Gemini API and Google AI Studio. Access is restricted to the API, meaning there are no open weights available for self-hosting. Enterprise access is expected to follow shortly.
The new models feature an expanded voice system compared to the previous version, which offered 30 original voices. Users can now influence speech delivery using natural script cues or specific stage directions embedded directly into the text. This allows for more precise control over the output style during the generation process.
For voice replication, the system requires a 30-second audio sample. Users must hold rights to the audio and provide a verbal consent recording from the voice owner to match the reference speaker. This process ensures that the generated vocal profile remains consistent with the original source material provided by the user.
Safety remains a priority for the new models. Every audio clip generated by the Gemini models includes a SynthID watermark, which is embedded directly into the output. Additionally, replicated voices are equipped with C2PA content credentials. Further details regarding the safety approach are available in the Gemini 3.8 Audio model card.



