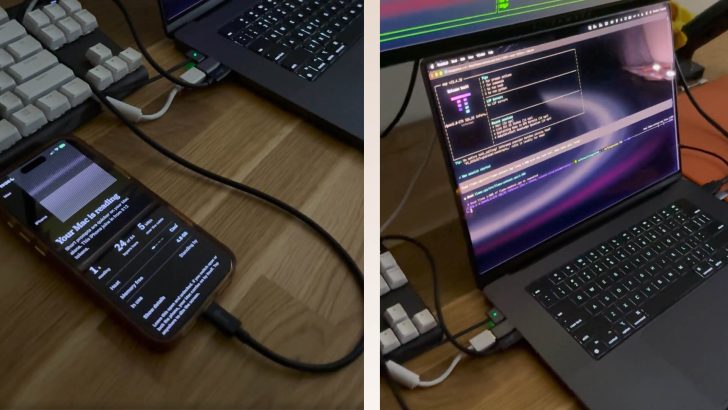
A Reddit user demonstrated a method to accelerate AI model inference by connecting an iPhone 17 Pro Max to a MacBook Pro with an M4 Pro chip. The setup uses custom software to split the workload of the Qwen3.8-27B model between the Mac and the iPhone, bypassing the 24GB unified memory limit of the laptop.
The process involves the MacBook Pro handling the first 40 layers of each 256-token batch, while the iPhone 17 Pro Max uses its A19 Pro GPU to process layers 41 through 64. This collaborative approach increased prefill speeds by up to 44% when the context window was set to 16K, improving performance from 109 to 157 tokens per second.
The system also utilizes the iPhone's Neural Engine to process older context data. At a 140K context length, the single-token write time decreased from 279 milliseconds to 176 milliseconds. However, the current implementation does not accelerate text generation, which remains solely on the Mac.
The software, named backburner, is available as an open-source project on GitHub. Future iterations may leverage the upcoming A20 Pro chip, which is expected to feature a dual 16-core Neural Engine with higher data throughput capabilities, potentially exceeding the performance of the integrated 7-core GPU.