

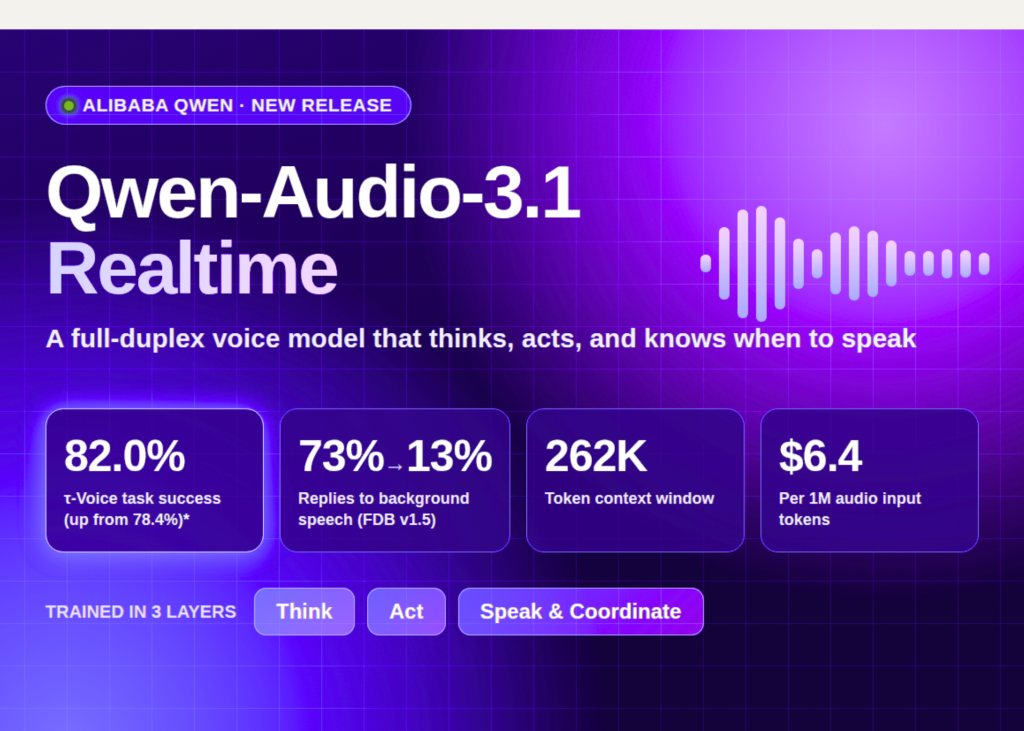
Alibaba has launched Qwen-Audio-3.1-Realtime, a full-duplex voice model available via a managed API on QwenCloud. The model supports both text and audio inputs and outputs, featuring a 262K token context window. Usage is limited to 60 requests and 100K tokens per minute.
Pricing for the model is set at $6.4 per 1M audio input tokens and $0.8 per 1M text input tokens. Output costs are $24 per 1M tokens, though output text is not charged. Key capabilities include function calling, web search, and structured outputs.
A secondary model, Qwen-Audio-3.1-ASR-Flash-Filetrans, is designed for offline transcription of long audio files. It supports multilingual recognition, speaker separation, and hot words. Pricing for this service is $0.15 per 1M input tokens and $0.47 per 1M output tokens.
The system architecture utilizes a decision model to manage full-duplex interactions, determining when to speak or stop. Training involved Core-Cocktail SFT and on-policy distillation. Performance metrics show an interruption stop latency of 1.116 seconds, compared to 0.383 seconds for GPT-Realtime-2.
Evaluation on Full-Duplex-Bench v3.0 showed a reduction in filler rates from 0.7590 to 0.2960. In human red-team testing, the model achieved a 92.00% score, while GPT-Realtime-2 scored 96.00%. No open weights have been released for the new models as of September 28, 2026.



