MIPT Researchers Unveil HARP Algorithm for LLM Compression
Researchers at MIPT have introduced the HARP algorithm, which enhances the performance of highly compressed large language models by reducing errors by up to 15%.
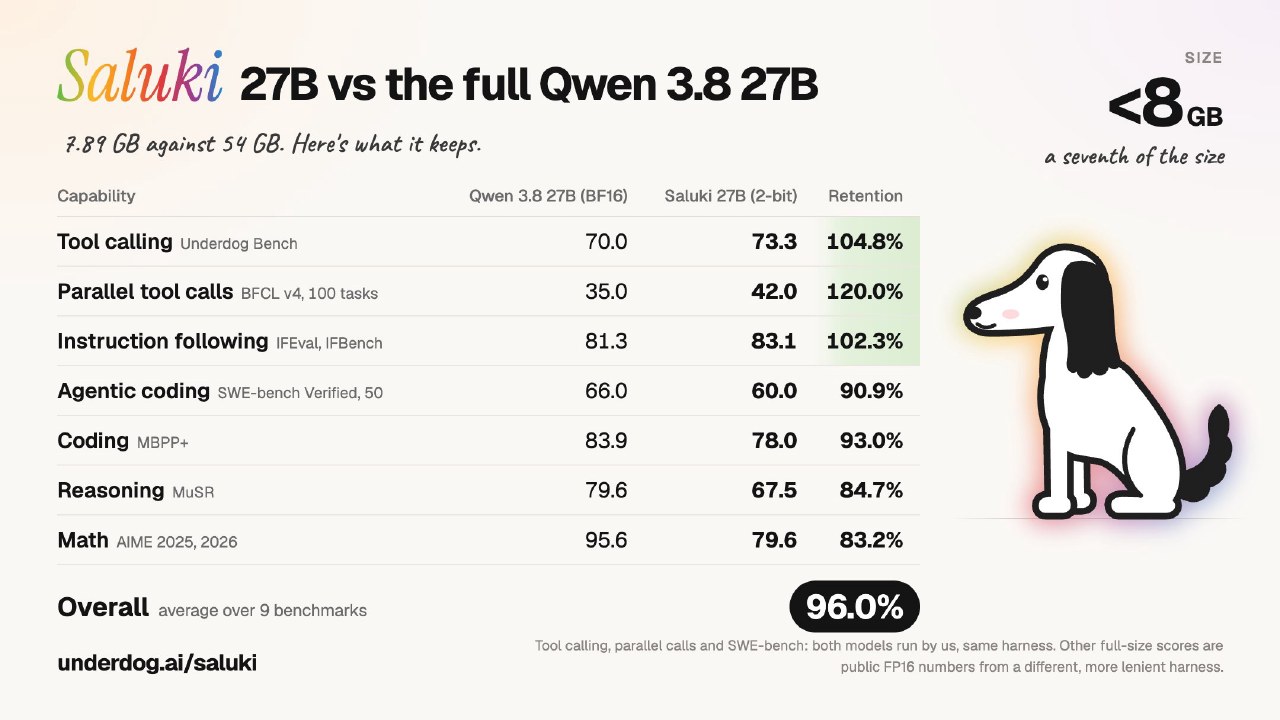
Underdog AI has released Saluki 27B, a 2-bit quantized version of Qwen3.8-27B designed for agent applications and efficient tool usage.

Conway Research has launched Saluki 27B, a 2-bit quantized version of Qwen3.8-27B that optimizes tool-calling performance while reducing file size to under 8 GB.
ExVRAM Lab has achieved 30 tokens per second for a 27-billion parameter model running entirely on an 8 GB consumer GPU by optimizing quantization and memory management.

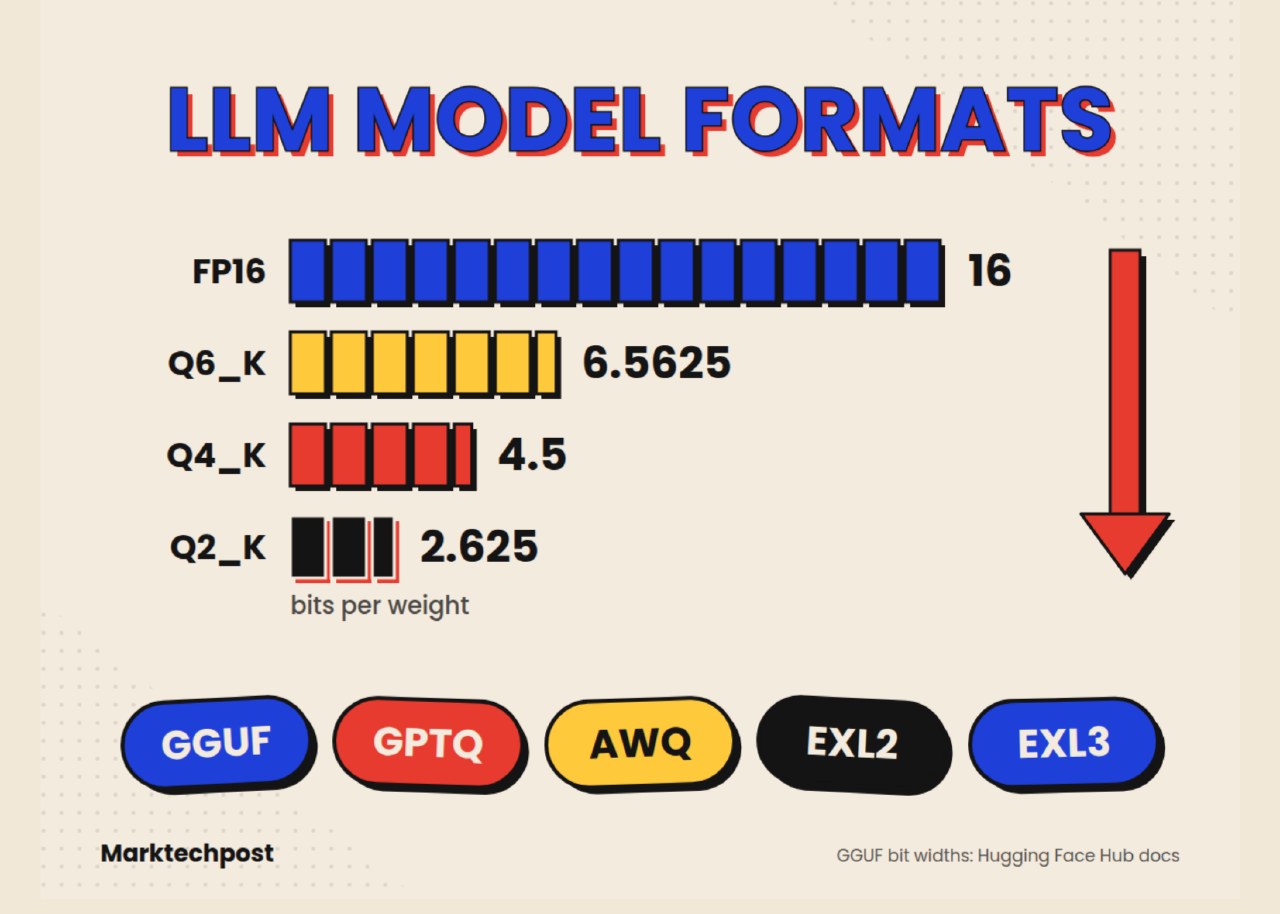
A technical overview of LLM model formats and quantization methods, including GGUF, GPTQ, AWQ, and EXL series, detailing their origins, technical specifications, and compatibility.

Neural network quantization and mixed-precision training optimize memory usage and computational speed, with hardware evolving to support specialized low-precision formats.