

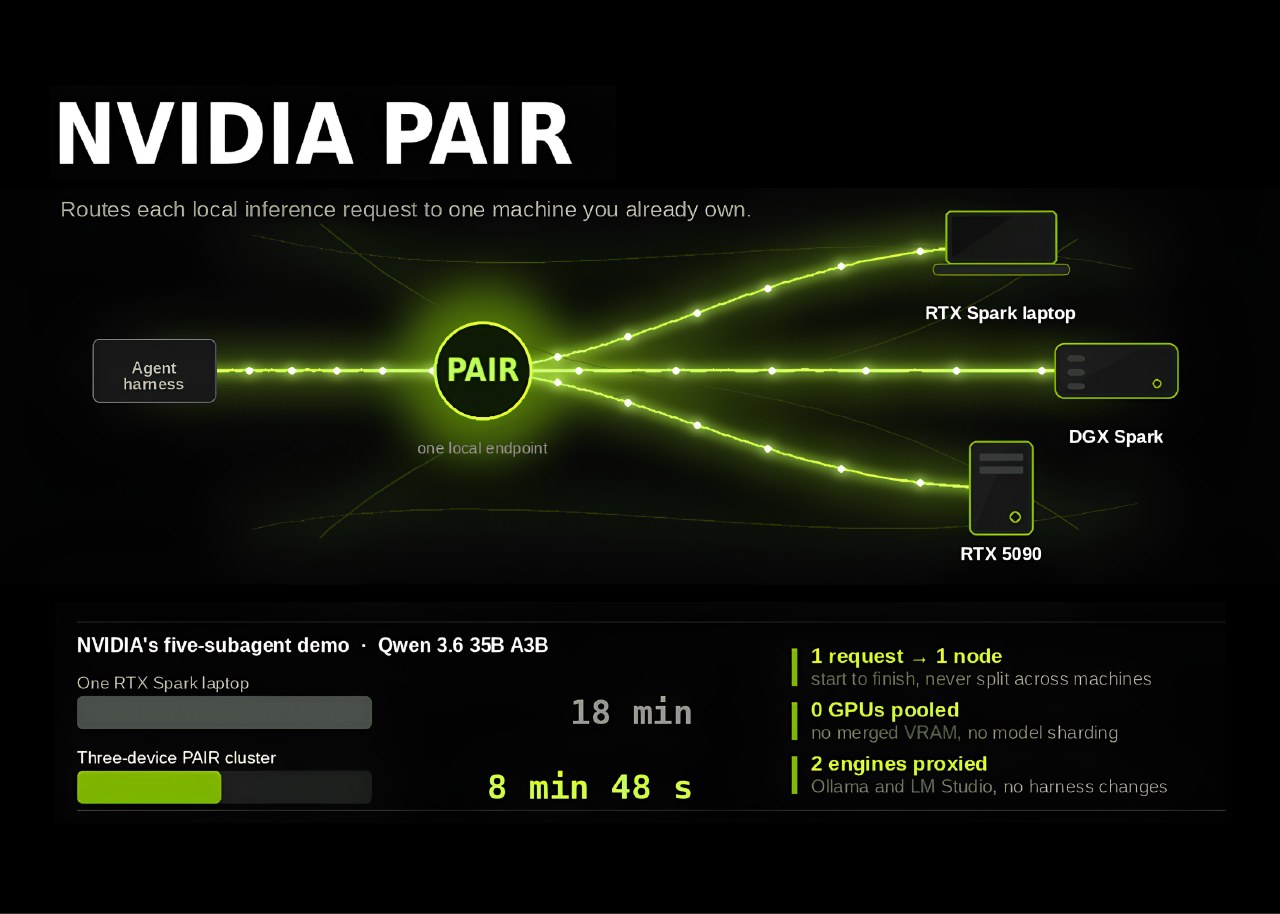
NVIDIA has launched the Personal AI Router (PAIR), an open-source virtual inference router designed to distribute local AI requests across multiple machines on a home network. The tool is currently available in public beta (v0.1.1) with installers for Windows, macOS, and Linux, and its source code is hosted on GitHub under the Apache 2.0 license.
The system operates as a proxy for Ollama and LM Studio interfaces, meaning existing agent harnesses require no changes. It uses mDNS for automatic discovery of nearby systems, with IP address addition as a fallback. Security is managed through a six-digit PIN for pairing and mTLS for node-to-node communication.
PAIR does not pool VRAM or shard requests across machines; instead, it assigns each request to a single eligible node based on five signals: online status, engine enablement, model presence, job load, and GPU utilization. The router can also automate the installation of engines and model downloads on paired systems.
In a demonstration with Hermes Desktop and the Qwen 3.6 35B A3B model, a workload that took 18 minutes on a single RTX Spark laptop was reduced to 8 minutes and 48 seconds on a three-device cluster consisting of an RTX Spark laptop, a DGX Spark, and an RTX 5090. Performance gains are achieved through workload-level concurrency.
The software supports GeForce RTX 20 Series and newer GPUs, RTX PRO workstation GPUs from Turing onward, DGX Spark, and Apple M4 or newer silicon. It is compatible with x64 and arm64 architectures on Windows, Linux, and macOS, with Windows on ARM being experimental. Recommended specifications include 8 GB of RAM or higher and 20 GB of disk space.



