Hermes Desktop is a free, MIT-licensed build of the open-source Hermes Agent. The application is compatible with macOS 12+, Windows 10/11, and all Linux distributions. It does not require an account to operate local models.
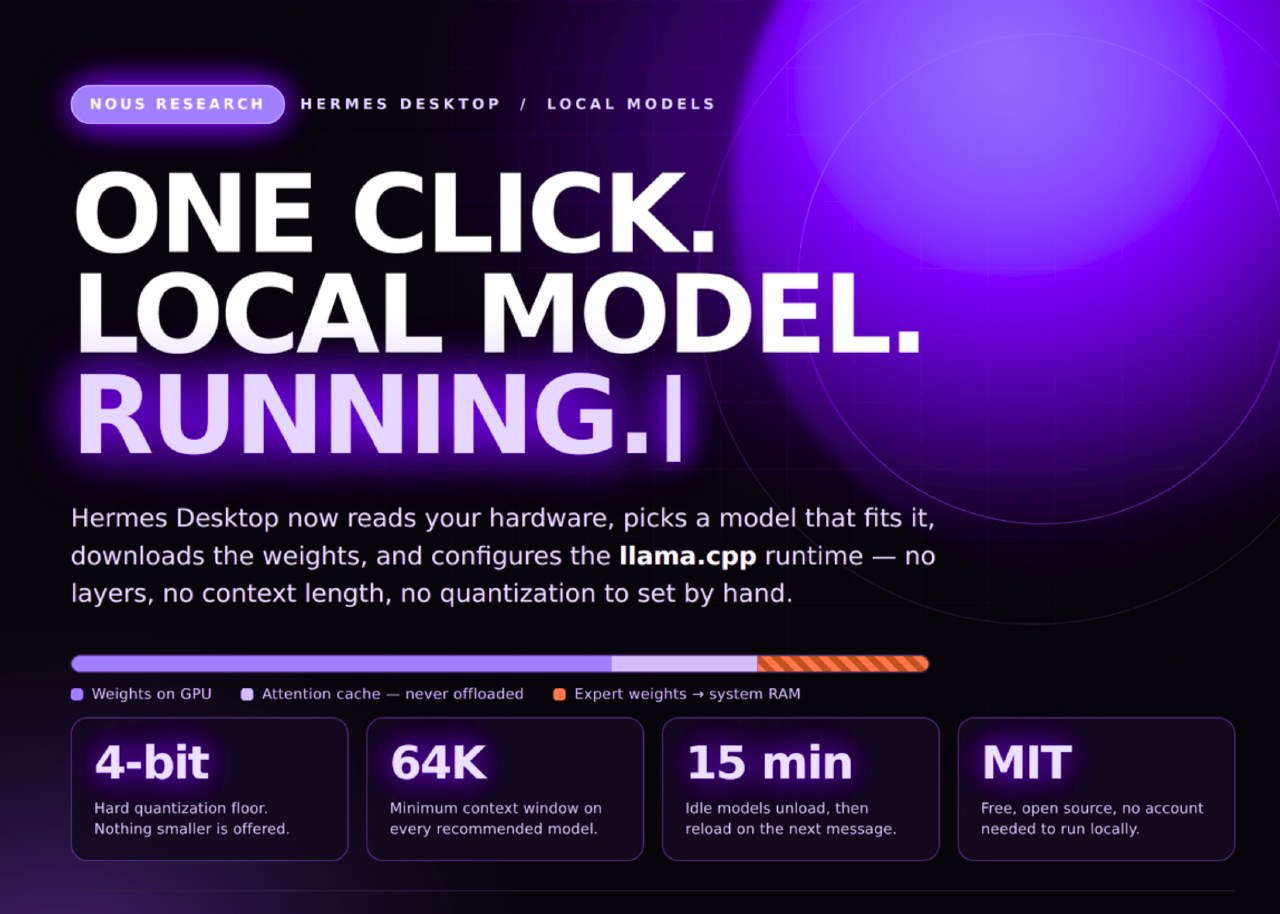
The new one-click setup automatically analyzes hardware, selects a suitable model, downloads it, and configures the runtime. This process triggers on the first launch or can be accessed via Settings → Providers → Local Models. The system manages the inference engine by fetching and updating a llama.cpp build tailored to the user's hardware.
The software supports CUDA, Metal, Vulkan, HIP, and CPU backends. It evaluates catalog models against the machine's specifications, marking them green if they fit in GPU memory, amber if they spill into system RAM, or red if they are too large. Users can see the download size and context window limits for each build.
Hermes selects the highest-quality build that fits entirely on the GPU, with a minimum quantization floor of 4-bit. Models that cannot run at 4-bit without spilling are marked as incompatible. Recommended models are guaranteed a context window of at least 64K.
When GPU memory is exceeded, the system offloads expert weights to system RAM first to protect the attention cache. Conversation compression only starts after the model reaches its maximum window. Idle models are automatically unloaded after 15 minutes and reload upon the next message.