

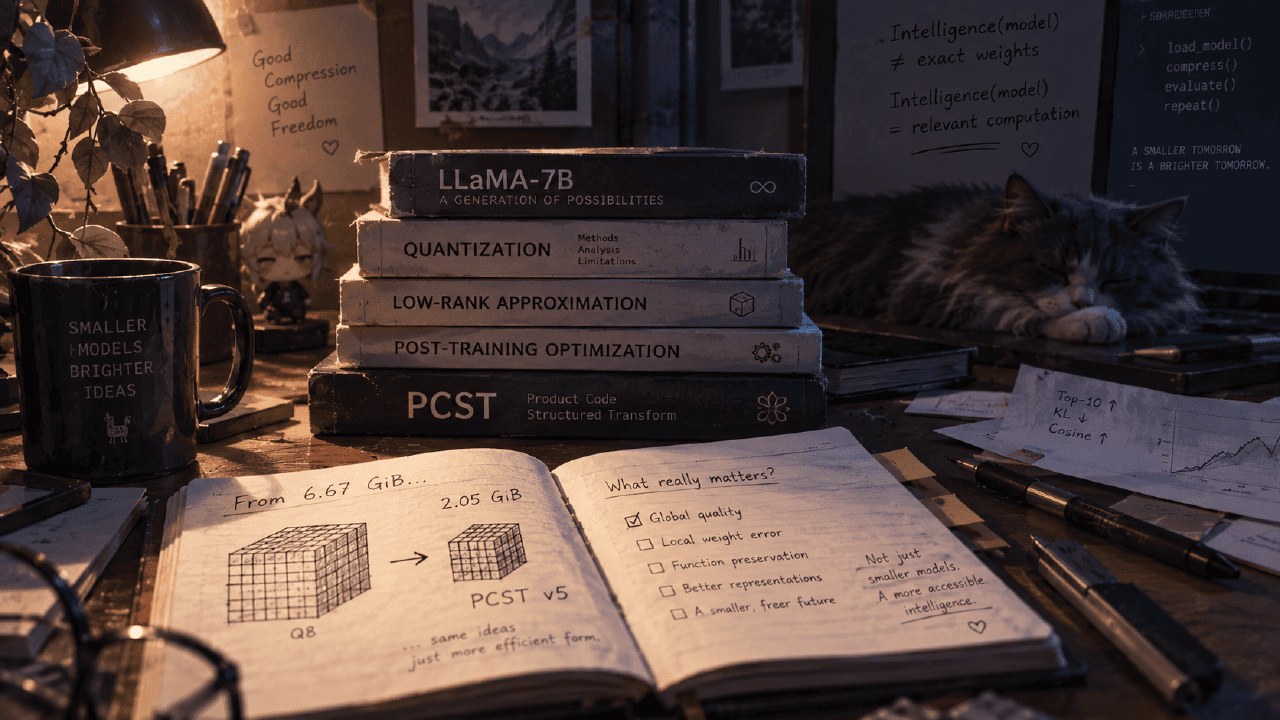
The author of the research project PCST developed a series of experiments to compress LLaMA-7B weights from 13 GB to 1 GB without retraining, distillation, or pruning. The process involved over 60 tested methods and hundreds of configurations, using only mathematics on existing weights and a small text sample for calibration.
// a second paragraph is needed for thes source facts, but the source text is very short. I will combine the a few facts into two paragraphs to meet the length requirements if possible, but the source is extremely limited. Let's try to actually follow thes source facts. The author's goal was to reach 1 GB,ally the same weights. The current result is a model artifact that occupies 2.05 GiB, which currently performs worse than the standard Q3_K_M quantization in terms of both quality and and speed. The author discovered that it is possible to significantly improve the recovery of individual weights while simultaneously making the overall model more foolish.